



Zak van der Merwe has spent his complete profession at AWS constructing management planes. First for EC2 and now for DSQL. On the floor, the management aircraft seems to be fairly boring: it data what ought to exist and reconciles that with what really does. No person leaves faculty dreaming of constructing one, however Zak would be the first to inform you that should you like fixing arduous issues in distributed techniques, there are few higher locations to be. It’s the place lots of these arduous issues converge, and the place the selections you make decide whether or not a service survives its personal development.
For those who’ve been following Marc Brooker’s and Marc Bowes’s writing on DSQL, this can be a nice companion piece that pulls again the curtain and exhibits what it means to construct a database that was designed from the beginning with management aircraft engineers in thoughts.
–W
On constructing scalable management planes
I’ve been working at AWS for practically fourteen years, and for nearly all of that point I’ve been constructing management planes. It’s not the form of profession anybody maps out for themselves. No person leaves college pondering “I need to spend the subsequent decade ensuring the bookkeeping layer of a cloud service stays up.” However right here I’m, and I feel the explanation I’m nonetheless right here is that management planes develop into the place lots of the attention-grabbing issues reside, even when it takes some time to see that clearly.
Earlier than Amazon, I labored at a telecoms firm in Cape City the place we had perhaps ten servers, all in a room at the back of the workplace, and each single one had a reputation. You’d SSH into them, you’d share them together with your colleagues, and if one thing went unsuitable you might stroll over and cope with it. That was my complete psychological mannequin of what it meant to run infrastructure. Servers had been stuff you knew individually, took care of intentionally, and will motive about as a set as a result of there have been few sufficient to slot in your head.
I point out this not as a result of it’s an uncommon background however as a result of it was so frequent lower than twenty years in the past, and I feel that’s what makes it price saying out loud. Possibly your model is a small Kubernetes cluster or a handful of RDS situations the place you’ll be able to visualize the entire thing, you’ll be able to identify the components, and when one thing breaks which half broke. That feeling of figuring out your infrastructure is snug, and it makes the subsequent a part of the story genuinely arduous to explain, as a result of what occurred once I joined EC2 was that that feeling simply evaporated.
Truthfully, once I began, I didn’t actually perceive how EC2 labored. I stored attempting to map it again to what I knew. If I launch an occasion and the underlying server dies, what occurs? Does my VM one way or the other get teleported onto one other host? How does the cloud create this phantasm that {hardware} failures don’t matter? I couldn’t sq. any of it with what I knew about working software program.
My first job at EC2 was health-checking the fleet, pinging each server and attempting to determine if it was wholesome or not, and what I discovered was the alternative of magic. Issues had been failing continuously. Hosts had been taking place, {hardware} misbehaving, disks dying. I had seen the underbelly of EC2 and it was chaotic. My psychological mannequin had gone from “servers are treasured stuff you defend” to “every thing is on fireplace on a regular basis.”
It took some time to shake that feeling, however what I might finally come to understand was that these failures had been tiny drops in an infinite ocean of issues working positive. The system was simply working at a scale the place failures had been a continuing, a statistical certainty fairly than an emergency. And the factor that made it potential to run a service at that scale with no human responding to each failure, the factor conserving every thing buzzing, was the management aircraft.
A method or one other, my years at AWS have been spent engaged on management planes. Each AWS service has one, and I like to think about them as our unsung heroes. The higher they work, the much less anybody notices them. They’re the explanation you don’t have to call your servers, and the explanation that when {hardware} fails, you as a buyer by no means need to cope with it. I’ve gotten to construct management planes for 2 main AWS companies: EC2, and DSQL. They’re practically a decade aside, but the arduous classes from constructing one led on to the design of the opposite, and that’s the story I need to inform as we speak.
What’s a management aircraft anyway?
At this level, I most likely owe you a greater clarification of what I imply by management aircraft and why I feel they’re attention-grabbing. I’ll use EC2 for instance, as a result of that’s the place I realized most of what I do know.
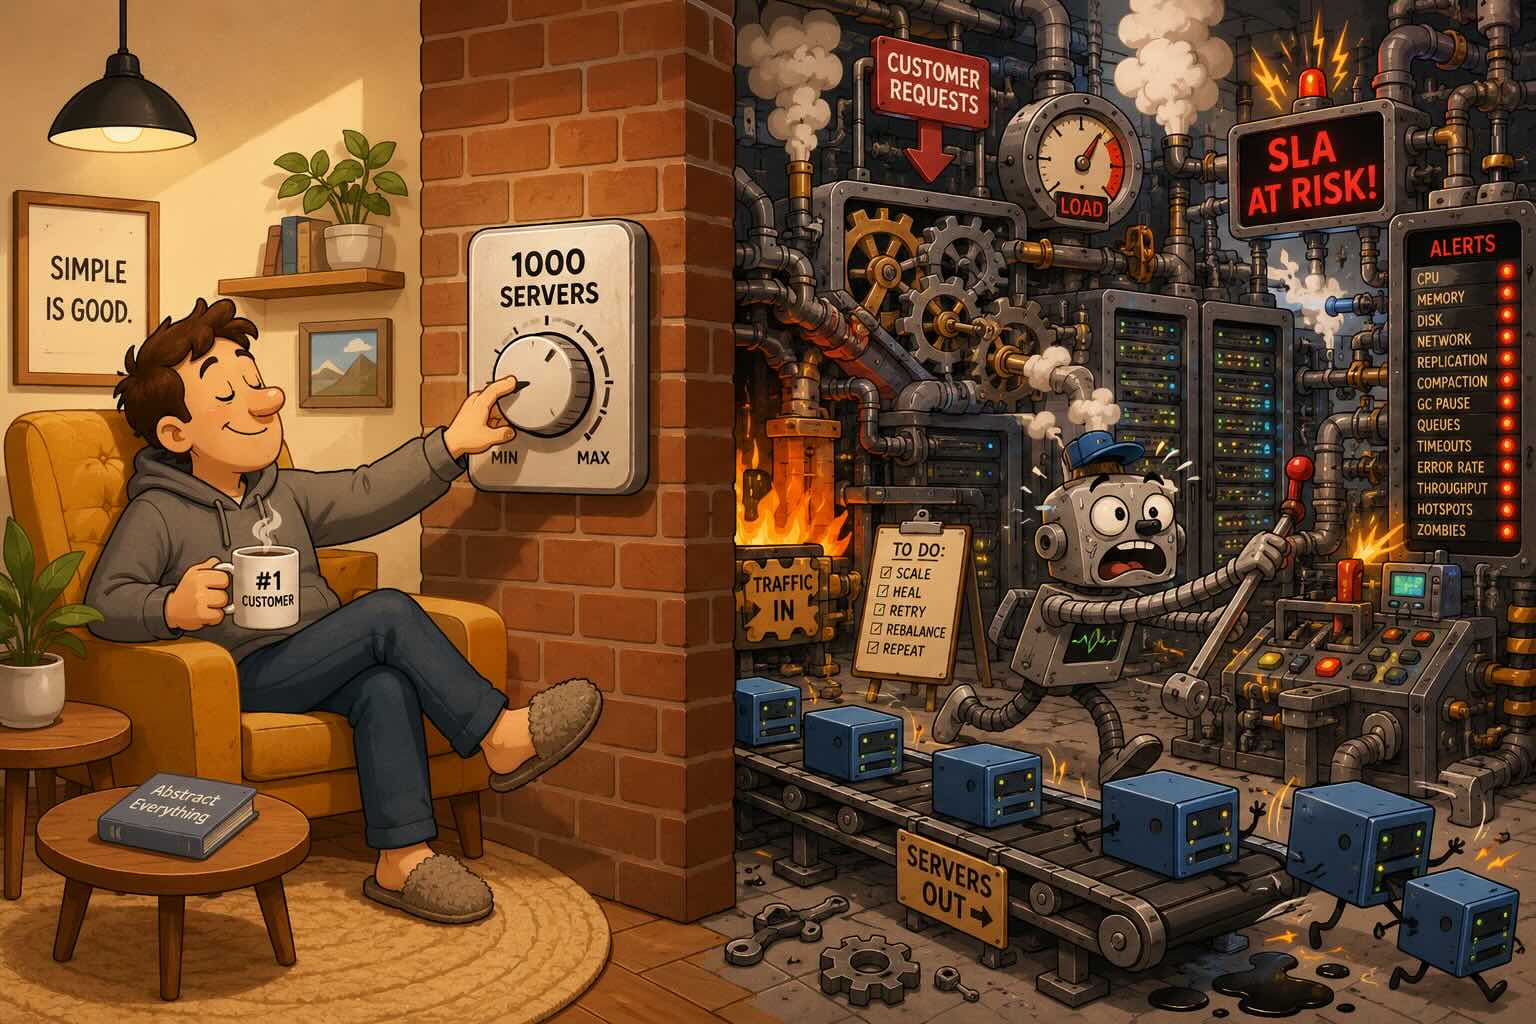
The best way I give it some thought is that each service has an information aircraft and a management aircraft. The information aircraft is the set of core capabilities, the uncooked computing energy, the {hardware}, the networking. The management aircraft is the conduit between these capabilities and prospects. It’s the factor that takes what exists bodily in an information middle and presents it to you in a format you’ll be able to really devour and get worth from. With out the management aircraft, you’d be again to SSH-ing into named servers in a closet someplace. With it, you’ll be able to spin up a thousand machines with an API name and by no means take into consideration the place they reside.

EC2 includes hundreds of engineers and extra options than anybody can hold monitor of, and but the management aircraft, conceptually… is fairly easy. Stripped down, EC2 enables you to hire a digital machine (VM) within the cloud, and the management aircraft’s job is to arrange and tear down these VMs for you.
I just like the analogy of a thermostat, as a result of it’s continuously measuring the temperature, it is aware of the place issues must be, and it’s all the time nudging the system in the fitting route. That’s what our management aircraft does. It’s a steady loop, watching the state of the world, evaluating it to what must be true, and correcting the distinction. If you launch a VM, the management aircraft data {that a} VM ought to exist, finds a bodily server in the fitting information middle, units up the picture, configures networking, and launches it. Later, if that server disappears for any motive, the management aircraft notices and updates its data to mirror actuality. It’s all the time reconciling what’s with what must be.
One factor the group talked about continuously, nearly to the purpose the place it grew to become a mantra, was that it doesn’t matter what occurs to the management aircraft, VMs which might be already working have to hold working. We name this static stability, and it sounds apparent due to course working VMs ought to hold working. However at scale, apparent issues are the toughest to guard, as a result of each new function, each change, each dependency is an opportunity to by chance violate that assure. Sustaining it’s the distinction between an outage the place prospects can’t launch new sources and an outage the place every thing stops. Each are unhealthy, however the second is catastrophically worse. The truth that EC2 was statically steady gave me some consolation in my early days.
The EC2 group has finished an outstanding job making unhealthy days uncommon. However understanding what unhealthy days seem like formed lots of what I find out about constructing management planes.
Dwelling contained in the management aircraft
To grasp how unhealthy days begin, it helps to know the way the management aircraft shops state. On the coronary heart of EC2’s management aircraft there’s a relational database. When prospects name the RunInstances API to launch a VM, essentially the most crucial factor that occurs is that the management aircraft writes a row into its database: buyer X now has VM Y. That’s when the API can safely return.
In actuality, a single RunInstances request triggers lots of or hundreds of inside API calls between micro and macro-services. Many of those companies have their very own databases recording their very own state. It’s arduous to magnify how advanced this has grown over time, however on the very backside of all that complexity, there’s a MySQL database, and what’s in that database is meant to match actuality.
The best method issues went unsuitable was additionally the scariest. Generally the first database server simply died. Our answer was a scorching standby, a backup server repeatedly replicating from the first, ideally solely milliseconds behind. When the first failed, we’d reduce over to the standby and it may restrict the outage to seconds. The group earned that by years of operational follow, constructing tooling, writing runbooks, coaching on-call engineers to execute the switchover below stress. However seconds of outage nonetheless meant pagers getting lit up at 3am and asking people to make choices with incomplete info. We stored asking ourselves whether or not the structure may take people out of that loop completely.
The slower, extra persistent downside was ensuring our MySQL database stored up with enterprise development. That is fairly irritating when you concentrate on it, as a result of the info aircraft does all of the heavy lifting, like downloading VM photos, configuring networking, working workloads, whereas the database is simply conserving monitor of what exists. Each occasion we launched meant extra inserts, extra updates, and extra reads in opposition to the database, and finally the bookkeeper couldn’t sustain with the employees.
So we launched extra servers replicating from the first and used these as learn replicas. Most of the EC2 APIs don’t make any adjustments, they simply describe the state of your present sources (what number of VMs do you will have, and so forth). We despatched site visitors for these read-only APIs to our new learn replicas and this massively decreased the load on our main database server. That is commonplace follow for any group attempting to scale up a relational database. By the way, this fleet of learn replicas is why the EC2 API is finally constant, and as Marc Brooker has written, this places an unlucky cognitive load on our prospects. It’s one thing we needed to do higher with DSQL, which we’ll get to in a bit.
Learn replicas purchased us time, however each write nonetheless funneled by a single main server, and finally we needed to shard the database. The primary part of this was seen to prospects as we cut up every AWS area into a number of availability zones (AZs), every with their very own unbiased management aircraft and separate MySQL databases. This helped with each scaling and availability, since zones fail independently and the blast radius of any single failure shrinks. It additionally grew to become a basic constructing block that permits AWS prospects to construct architectures resilient to the lack of a single AZ. The second part was inside: we sharded every zone into what we name cells. Each of those tasks took years of engineering time as a result of they required adjustments throughout many companies. Each place within the codebase that talks to the database has to know which shard to path to. Easy lookups by main key are simple, however the rest, akin to joins throughout information that doesn’t align together with your sharding boundaries, will get a lot trickier. Even the best choices have penalties at this degree. Do you shard by account or by useful resource? Completely different companies select otherwise relying on their entry patterns, and there’s no universally proper reply.
There may be additionally a human price to all of this that I don’t assume we speak about sufficient. In these early years, we didn’t have the automation to deal with lots of what a contemporary management aircraft simply takes care of. When a safety vulnerability was found and the entire fleet wanted to be patched, we didn’t have a system that might say “go replace each host at a protected fee.” We might actually recruit the entire group, subdivide all of the hosts, and assign shifts. Everybody within the Cape City workplace would get a piece. Go replace each certainly one of your hosts, report standing. That’s what life seems to be like with no mature management aircraft, and it’s the form of factor that doesn’t scale. You possibly can patch a fleet of some hundred hosts that method. You can’t patch a fleet of thousands and thousands that method. The management aircraft is what finally bought people out of that loop completely.
For those who’ve lived by this development, the scaling cliffs, the learn duplicate tradeoffs, the sharding tasks that all the time take longer than you assume they may, it’s a protracted and painful highway, and it’s one that each group constructing a profitable service backed by a relational database finally walks.
Looking for Database Xanadu
After a decade engaged on EC2, I fashioned some robust opinions on what my ideally suited database seems to be like. It scales with my enterprise with out heroics. It’s extremely obtainable with no downtime for updates, and no servers to babysit. My ideally suited database lets me leverage the facility of the relational information mannequin to mannequin my area and write software program extra productively.
Because it seems, within the early 2020s, a bunch of skilled engineers on the databases aspect of AWS had been excited about precisely learn how to construct this kind of database. These engineers had been expats from companies like EC2 and had felt the ache of working relational databases firsthand. They had been additionally trying on the classes realized working large scale serverless databases like DynamoDB and dreaming up methods to use them to relational databases.
They needed to do for databases what EC2 and actually Lambda did to servers. For those who function a standard database with a “head node” you might be on the earth of “servers with names” like I used to be earlier than becoming a member of EC2. The perfect database would free you from excited about “databases with names”. As an alternative, it will have a management aircraft that takes care of all of that for you in an effort to simply take into consideration your database as a logical endpoint that’s all the time obtainable whereas it scales up and down.
Someday round 2021, this challenge actually began to choose up steam. We’d discovered an structure which appeared to ship on this promise of the best database. I bought the chance to affix the group and begin constructing its management aircraft. This service would launch in GA as Amazon Aurora DSQL in 2025.
Let’s rapidly revisit the main ache factors that EC2 went by and see how life is completely different on DSQL—particularly for management aircraft builders.
In DSQL, there isn’t one server working your database. DSQL spins up a Firecracker micro-VM per connection, which implies each connection is its personal small head node. If one fails, solely that single connection is affected fairly than your entire software. No person will get paged, nobody has to determine to chop over. I don’t handle standbys anymore, as a result of the structure has eliminated people from that painful loop completely.
Scaling reads was one other downside we spent years on at EC2, including replicas by hand and accepting eventual consistency as the associated fee. DSQL provides learn replicas robotically, and in reality this is without doubt one of the main jobs of the management aircraft that I helped construct. In case your software abruptly sees a spike in learn site visitors, DSQL handles it, and the reads are strongly constant, all the time. After years of telling prospects “attempt once more in a second,” this property nonetheless blows my thoughts. It essentially simplifies the structure of any management aircraft constructed on DSQL, and it removes that cognitive tax from the builders utilizing the APIs these management planes expose.
After which there’s sharding, which was availability zones and cells at EC2 and took us years. If you construct AWS management planes for main new companies, it’s a must to anticipate that sharding will grow to be needed, and expertise has proven that it’s cheaper to do it from the beginning than to retrofit it later. That is an unsightly dilemma, since you’re extending your time to market on a speculative future downside, and when supply timelines get tight, I’ve seen many groups surrender on sharding simply to ship. DSQL removes that dilemma as a result of it robotically partitions your workload and also you don’t have to consider it. You should utilize all of the Postgres goodies you’re used to, advanced transactions, multi-table joins, secondary indexes, whereas figuring out your database goes to scale together with your wants. Many new AWS management planes over the past decade had been constructed on DynamoDB for this similar motive, however DSQL presents a world with fewer compromises. You get the scalability of DynamoDB with the relational programming mannequin that builders really choose to work with.
“Self-hosting”
When it got here time to decide on a database for the DSQL management aircraft, we selected DSQL. A group that runs by itself product feels each tough edge earlier than its prospects do, however getting there meant taking up the identical round dependency we’d confronted at EC2: a management aircraft can’t rely upon the factor it controls.
We’ve seen two important advantages from the choice to “self-host”. As prospects undertake DSQL, they’re creating hundreds of databases, and the management aircraft is repeatedly scaling their databases up and down primarily based on utilization, typically very quickly. All of this buyer exercise creates “bookkeeping” work for the DSQL management aircraft, and the quantity of this work grows with DSQL adoption. For the reason that DSQL management aircraft runs on DSQL, our bookkeeping database scales as much as sustain with this enhance in demand with minimal work from the group.
The opposite profit is in how we cope with availability zone outages. DSQL was designed from the bottom as much as survive single zone failures, however simply because a zone is down doesn’t imply that buyer workloads cease scaling or that prospects cease creating databases. In my EC2 days, zone failures had been fireplace storms as management aircraft databases died and pagers went off. For the DSQL management aircraft, these unlucky unhealthy days are a lot much less painful as a result of the DSQL management aircraft’s database stays obtainable which permits the management aircraft to maintain doing its crucial work that ensures buyer databases hold chugging alongside.
Taking off the rose-tinted glasses
For those who’re nonetheless with me, you’re most likely pondering to your self: “what’s the catch?”
As a comparatively new service, there are options that we simply don’t assist but. A few of these are gaps that we’re actively filling. Others are extra nuanced, and we need to take our time to verify we construct the fitting factor. A very good instance is overseas key constraints. International key constraints are a basic database function that may be very helpful and aren’t essentially arduous to implement. Nevertheless, overseas keys will also be harmful at scale. We need to get this proper, and that takes time.
One of many benefits of working Postgres on a single node is that it maintains the working set in reminiscence, and cached reads are insanely quick. Actual architectures are extra sophisticated although. For instance, a management aircraft utilizing Postgres would run throughout a number of availability zones and put a connection multiplexing proxy in entrance of the database. These are needed steps for availability and scale, however they enhance latency. If you construct on DSQL, you don’t have to handle these items your self. You get good (although not fairly single-node Postgres good) latency that continues to be constant as your software scales. That is precisely what I need as a management aircraft builder. Sure, I need quick, however I care much more about predictable latency as my software scales.
It’s additionally price being sincere about the place issues stand for management aircraft builders at AWS. Migrating one thing like EC2’s management aircraft onto DSQL would take years even when we began as we speak, and that’s okay. The ten-odd years I spent on the EC2 management aircraft taught me that the work that issues most tends to measure its impression in years, not quarters.
Wanting round corners
We’ve spent most of this publish deep in database scaling and life assist. It’s a well-recognized form for lots of engineering tales. The issues we confronted at EC2, learn how to go sooner with out breaking issues, learn how to spend extra of our time on the issues that matter to prospects, learn how to coordinate throughout a group that grew from a handful of individuals to hundreds, and learn how to hold the system dependable whereas the bottom shifted beneath us, are the identical issues each engineering group runs into because it scales. They’re shut cousins of the issues that produced Amazon’s authentic distributed computing manifesto again in 1998, and my very own focus narrowed over time to a single model of them, which was learn how to let particular person groups absolutely personal a bit of EC2 and transfer quick on their most pressing issues with out costly coordination, all whereas the product nonetheless felt like one coherent factor to a buyer.
Once I have a look at the broader trade as we speak, I see echoes of that very same stress enjoying out at a scale I didn’t count on, as a result of the arrival of agentic coding has pushed the price of writing software program all the way down to nearly nothing, and that pushes the arduous a part of the work someplace else. When code is reasonable, the bottleneck strikes to judgment, to determining what to construct, learn how to ship it safely, and learn how to anticipate what your prospects will want earlier than they ask. That’s the similar shift a great management aircraft makes for the individuals who construct on it, taking the invisible work of conserving infrastructure alive off their plate to allow them to spend their consideration on their prospects, solely now it’s occurring to software program improvement as a complete, and even a single-person group feels the necessity to scale out.
I’m not going to fake I do know what constructing software program will seem like a yr from now, as a result of we’re in the course of a rework and the partitions are nonetheless open. What I do know is that it’s a lot simpler to maneuver quick if you find yourself standing on a basis that won’t crack below you, and that the issues price spending a profession on have all the time been those that want your judgment fairly than your capability to maintain the bookkeeping layer from falling over. My hope is that DSQL offers the subsequent era of builders that basis, and provides them again the time to go go searching corners for his or her prospects, which is the half I all the time wished we had extra room for at EC2.
And as Werner says: “Now, go construct.”