


In March, we wrote that Studying Labs would add GPU-backed environments so learners might run Cisco’s personal AI fashions hands-on. The primary two of these labs at the moment are dwell, constructed on Antares. This submit covers the labs first, then goes behind the scenes on how the platform runs GPU workloads. If you happen to’re right here for the safety labs, the primary half is all you want.
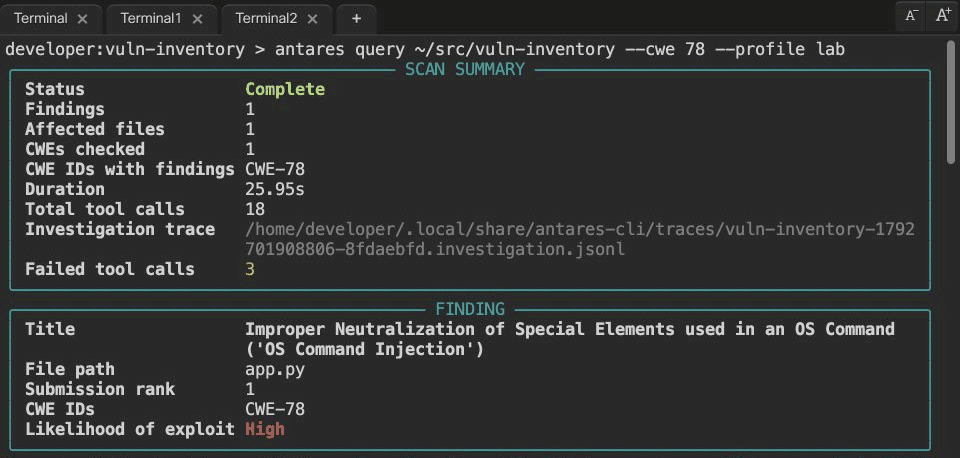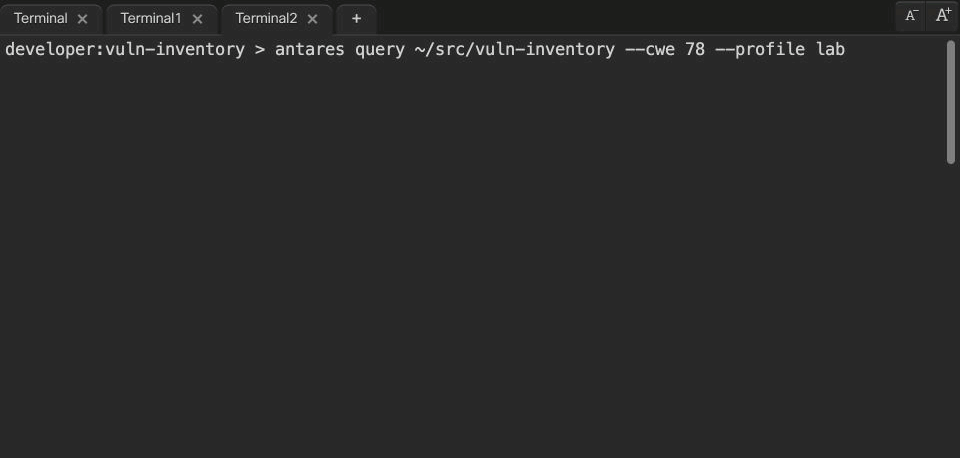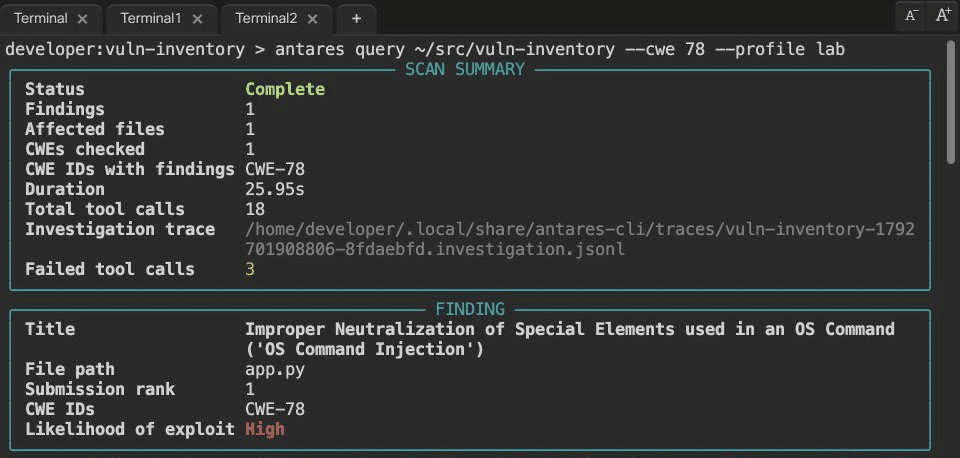
Antares-1B returns app.py as a command-injection candidate for assessment within the native DevNet GPU lab. This NVIDIA A10G run took 25.95 seconds; playback is condensed to 4.5 seconds. Do this lab
What Antares Does
Discovering the place a identified sort of vulnerability truly lives in a big codebase normally means studying it file by file or sending your code to a big cloud mannequin. Antares removes each constraints. It’s a household of compact, open-weight fashions from Cisco Basis AI, sufficiently small to run on a single GPU. They do one job: vulnerability localization. You give Antares a weak point sort, written as a CWE (a normal class of software program weak point, comparable to CWE-78, OS command injection), and it really works out which recordsdata in a codebase might comprise it.
Antares doesn’t scan code the way in which a static analyzer does, making use of mounted guidelines in a single cross. It really works as an agent that investigates iteratively, the way in which a human reviewer works via an unfamiliar repository. Every step is chosen from what the final one revealed: it searches for related code patterns, reads the candidate recordsdata, folds within the new proof, and follows leads from one file to the subsequent. When a path seems to be unproductive, it adjustments path, narrowing towards the recordsdata more than likely to matter till it has sufficient proof to reply. Ask it to search for command injection (CWE-78), for instance, and it searches for calls like os.system, opens app.py to see the place the enter comes from, and studies that file together with why it could be weak.
Regardless of its measurement, Antares holds its personal towards a lot bigger fashions on vulnerability localization (see the mannequin card for benchmark particulars). It’s constructed as a quick, personal pre-filter: it narrows a big repository all the way down to a brief record of candidate recordsdata for a human analyst, and your supply code by no means has to depart your surroundings when the mannequin and investigation instruments are hosted there.
Two Labs: Scan Code for Vulnerabilities on a GPU
In each labs, you level Antares at a codebase and a weak point sort, and it tells you which recordsdata more than likely comprise it, and why. Mannequin inference runs on a GPU in Cisco’s hosted, browser-based lab surroundings, and repository inspection runs there too. Every lab takes about 45 minutes (excluding mannequin downloads) and requires a free Hugging Face account with authorized entry to the gated Antares fashions. The identical steps work on any GPU-enabled host, so you possibly can take what you study to your individual surroundings.
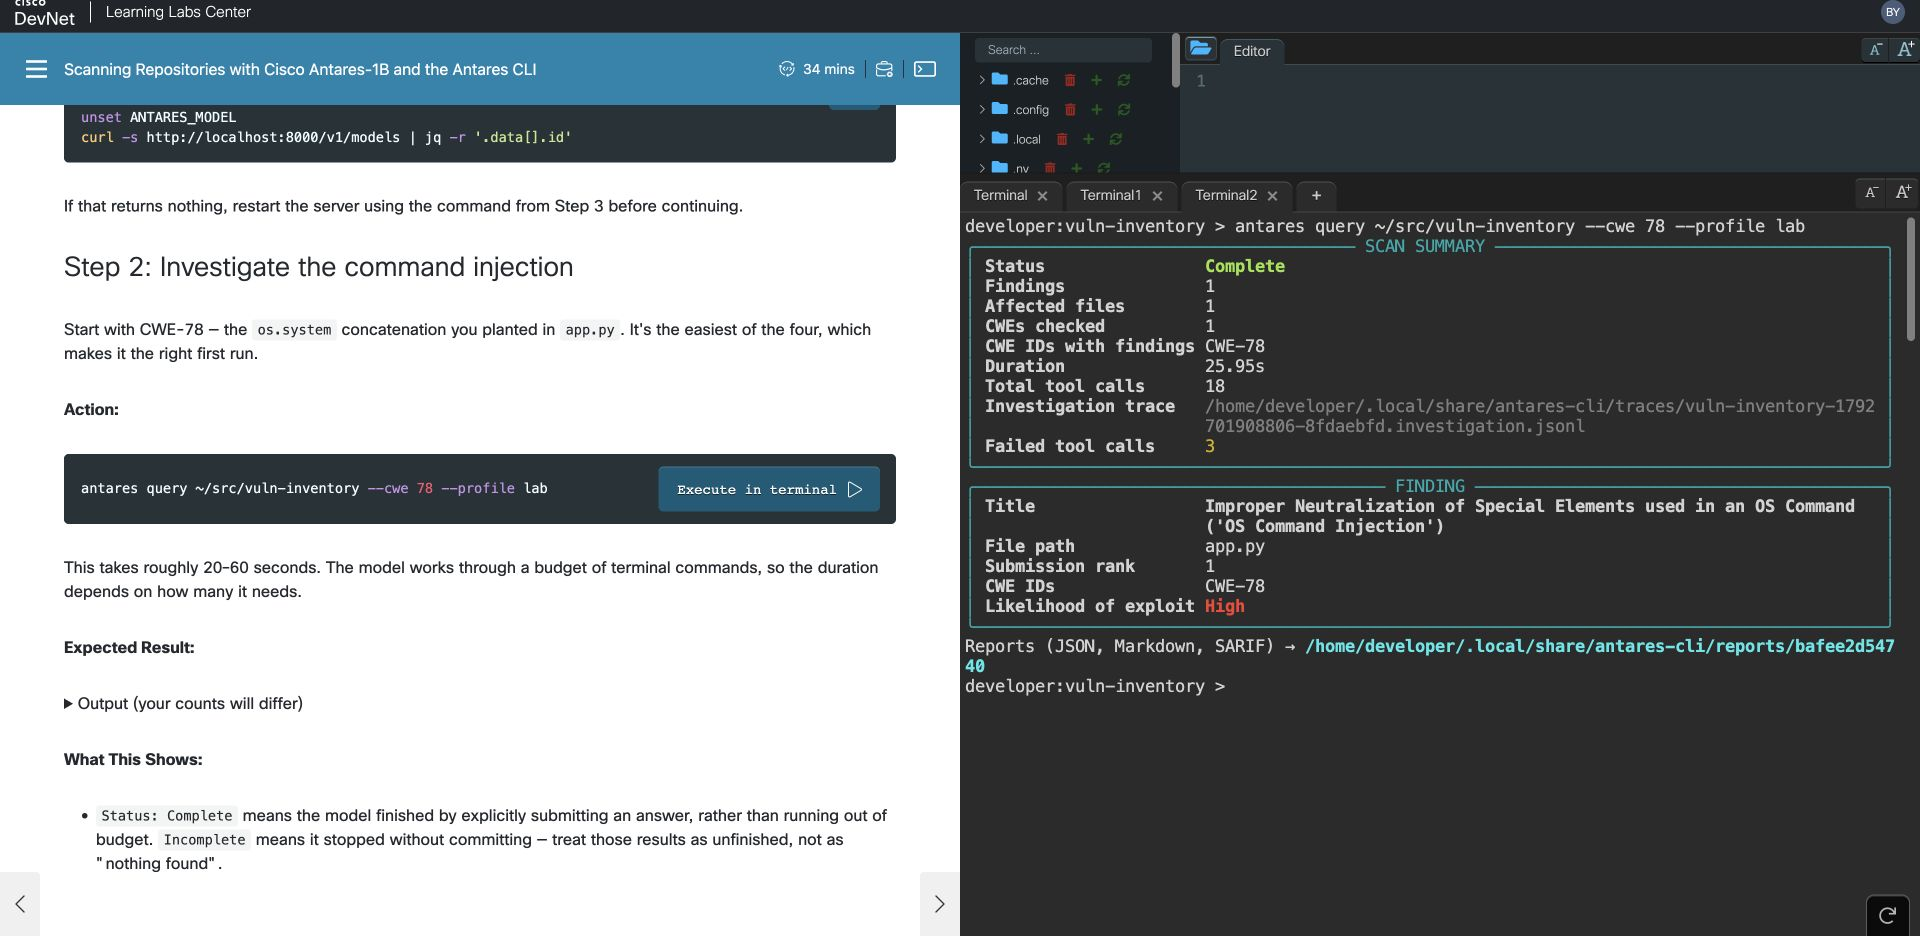
The native DevNet lab pairs the revealed question step with its accomplished Antares-1B output within the terminal.
Deal with what Antares returns as candidates to confirm, not confirmed findings. Like all localization mannequin, it may miss a weak file or flag a clear one. It really works finest alongside static evaluation and guide assessment, not instead of them, and each labs present you learn how to examine its work.
Antares Getting Began: Construct Your Personal Vulnerability-Searching Agent
In this lab, you’ll construct a working vulnerability-localization agent from scratch. You load antares-1b, write a small Flask app containing an OS command injection flaw (CWE-78), and code the agent loop that lets the mannequin search it. Then you definitely watch Antares hunt, one flip at a time: what it’s considering, the command it runs, and what comes again. It ends by naming the file it believes is weak and explaining why.
By the tip, you’ll have the ability to:
- Search a codebase for a selected weak point sort (a CWE) and get again the probably file with a plain-language rationalization.
- Perceive how an AI safety agent works beneath the hood, slightly than treating it as a black field.
- Preserve the agent scoped to the code you’re scanning, utilizing easy guardrails that refuse instructions attempting to learn exterior the repository.
- Confirm the outcome your self earlier than trusting it, which is precisely how a safety analyst makes use of a quick pre-filter like Antares.
Antares CLI: Scan a Repository the Method You Would in CI
In the second lab, you’ll scan a repository with a number of planted vulnerabilities utilizing Cisco’s official Antares CLI, served on the GPU with vLLM. You’re employed via the three instructions you’d use on an actual undertaking:
- antares plan profiles the repository and recommends which weak point sorts are value checking, earlier than utilizing any GPU time.
- antares question investigates one weak point. Within the lab, it returns a command-injection candidate in app.py in about 24 seconds.
- antares sweep checks each really useful weak point in parallel and writes studies in JSON, Markdown, and SARIF, the format CI pipelines and code-scanning dashboards already learn.
By the tip, you’ll have the ability to:
- Scan a complete repository for the weak point sorts that matter to it with one command and assessment the findings.
- Plug the outcomes into CI utilizing SARIF output.
- Learn a scan the way in which an analyst would, together with checking which weak point sorts had been chosen earlier than concluding something was missed.
- Scan code you didn’t write, with guardrails in place. The CLI works on a read-only snapshot, permits solely allowlisted read-only instructions, blocks shell growth, and quarantines prompt-injection makes an attempt hidden within the scanned code.
Behind the Scenes: GPU Labs on the DevNet Platform
This half is for readers enthusiastic about how the platform runs GPU labs at scale.
Time-Slicing on Shared Nodes
GPU labs run on AWS g5.2xlarge cases, every with a single NVIDIA A10G (about 23 GiB of VRAM). Every lab surroundings will get a slice of that GPU, configured for 3 time-sliced replicas per bodily GPU. Time-slicing splits compute time, not reminiscence. All three learners share the identical VRAM pool with no laborious boundary between them, and that turned out to matter. (The A10G doesn’t help MIG, so {hardware} partitioning isn’t an choice on this node sort.)
For the cluster mechanics, together with Kubernetes scheduling, time-slicing configuration, and Karpenter, see our GPU collection: Half 1 and Half 2.
Three Learners, One GPU
Earlier than publishing, we constructed a benchmark harness that runs every lab finish to finish via the similar path an actual learner makes use of, over the Istio gateway and WebSocket. It runs waves of concurrent lab environments and data completion, step timing, CPU, reminiscence, disk, and per-process GPU telemetry.
Each labs accomplished with three learners working directly on a single GPU. In Getting Began, every learner acquired near an excellent third of the GPU’s compute.
The CLI lab wanted one repair to get there. Each learner begins their very own vLLM server, and vLLM cases don’t coordinate GPU reminiscence with one another (vllm#10643). By default, every server sizes its KV cache from no matter reminiscence seems free at startup. When three begin directly, every sees reminiscence the others are about to say; they over-commit, and sometimes just one comes up (“No out there reminiscence for the cache blocks”).
The repair takes two flags, as a result of vLLM makes two separate reminiscence selections at startup:
- –kv-cache-memory 3120851354 fixes every server’s KV cache at 2.91 GiB, as a substitute of sizing it from free reminiscence. With nothing to measure, there’s nothing to race over.
- –gpu-memory-utilization 0.30 remains to be required. Even with a set KV cache, vLLM checks at startup that free reminiscence covers its utilization goal, which defaults to 90% of the cardboard. At a 92% goal, for instance, as soon as one server is up, that examine fails for the subsequent one with this error: “Free reminiscence on machine cuda:0 (17.96/22.06 GiB) on startup is lower than desired GPU reminiscence utilization (0.92, 20.29 GiB).” Setting the goal to 30% lets every server begin with its friends already resident.
With each flags, all three engines begin collectively and full the complete lab.
GPU as a Property of the Lab
On the platform facet, a lab creator doesn’t contact GPU configuration. The lab declares a GPU-enabled picture; the Studying Labs surroundings service schedules it onto the GPU node pool and releases the slice when the session ends. Learners simply run nvidia-smi and begin working.
Authoring with AI, Reviewed by Specialists
We drafted each labs with an AI lab-authoring talent that encodes the Studying Lab construction and DevNet’s authoring fashion, and safety subject-matter consultants reviewed and refined them. We captured each anticipated output within the labs from an actual run on a GPU; none of it’s generated.
What’s Subsequent
- Basis-sec-8b: a lab working Cisco’s safety basis mannequin on the identical GPU infrastructure is subsequent.
Strive the labs and inform us what you’d prefer to see subsequent.
Because of Didier Chapoteau and Barry Yuan for reviewing and refining the lab content material, Matt Shooshtari for GPU and CUDA configuration, Jerry Chang for GPU cluster automation, and Angellee Li for Studying Labs platform help.