


Why do Transformer fashions like BERT use GELU as an alternative of the standard ReLU activation operate? The reply lies in how these capabilities course of info. Whereas ReLU fully removes unfavourable inputs, GELU makes use of a easy, input-dependent mechanism to resolve how a lot info ought to move by way of. This small mathematical distinction can affect how neural networks be taught complicated patterns.
On this article, we are going to perceive the GELU activation operate, discover its arithmetic, examine it with ReLU, and implement each capabilities utilizing Python.
What Is the GELU Activation Perform?
GELU stands for Gaussian Error Linear Unit. It’s a nonlinear activation operate launched by Dan Hendrycks and Kevin Gimpel in 2016.
An activation operate determines how a neuron transforms its enter earlier than passing info to the following layer. With out nonlinear activation capabilities, stacking linear layers would nonetheless produce an total linear transformation, limiting what a neural community may be taught.
GELU takes a unique strategy from conventional activation capabilities. As an alternative of making use of a tough threshold, it easily scales every enter primarily based on its worth.
The instinct is straightforward:
- Sturdy constructive inputs are handed by way of virtually unchanged.
- Inputs near zero are partially suppressed.
- Sturdy unfavourable inputs are pushed towards zero.
- Reasonably unfavourable inputs can retain a small unfavourable output.
The unique GELU paper evaluated the operate throughout pc imaginative and prescient, pure language processing, and speech duties and reported enhancements over a number of conventional activation capabilities in its experiments.
Understanding GELU vs ReLU Visually
ReLU stands for Rectified Linear Unit. Its mathematical definition is:
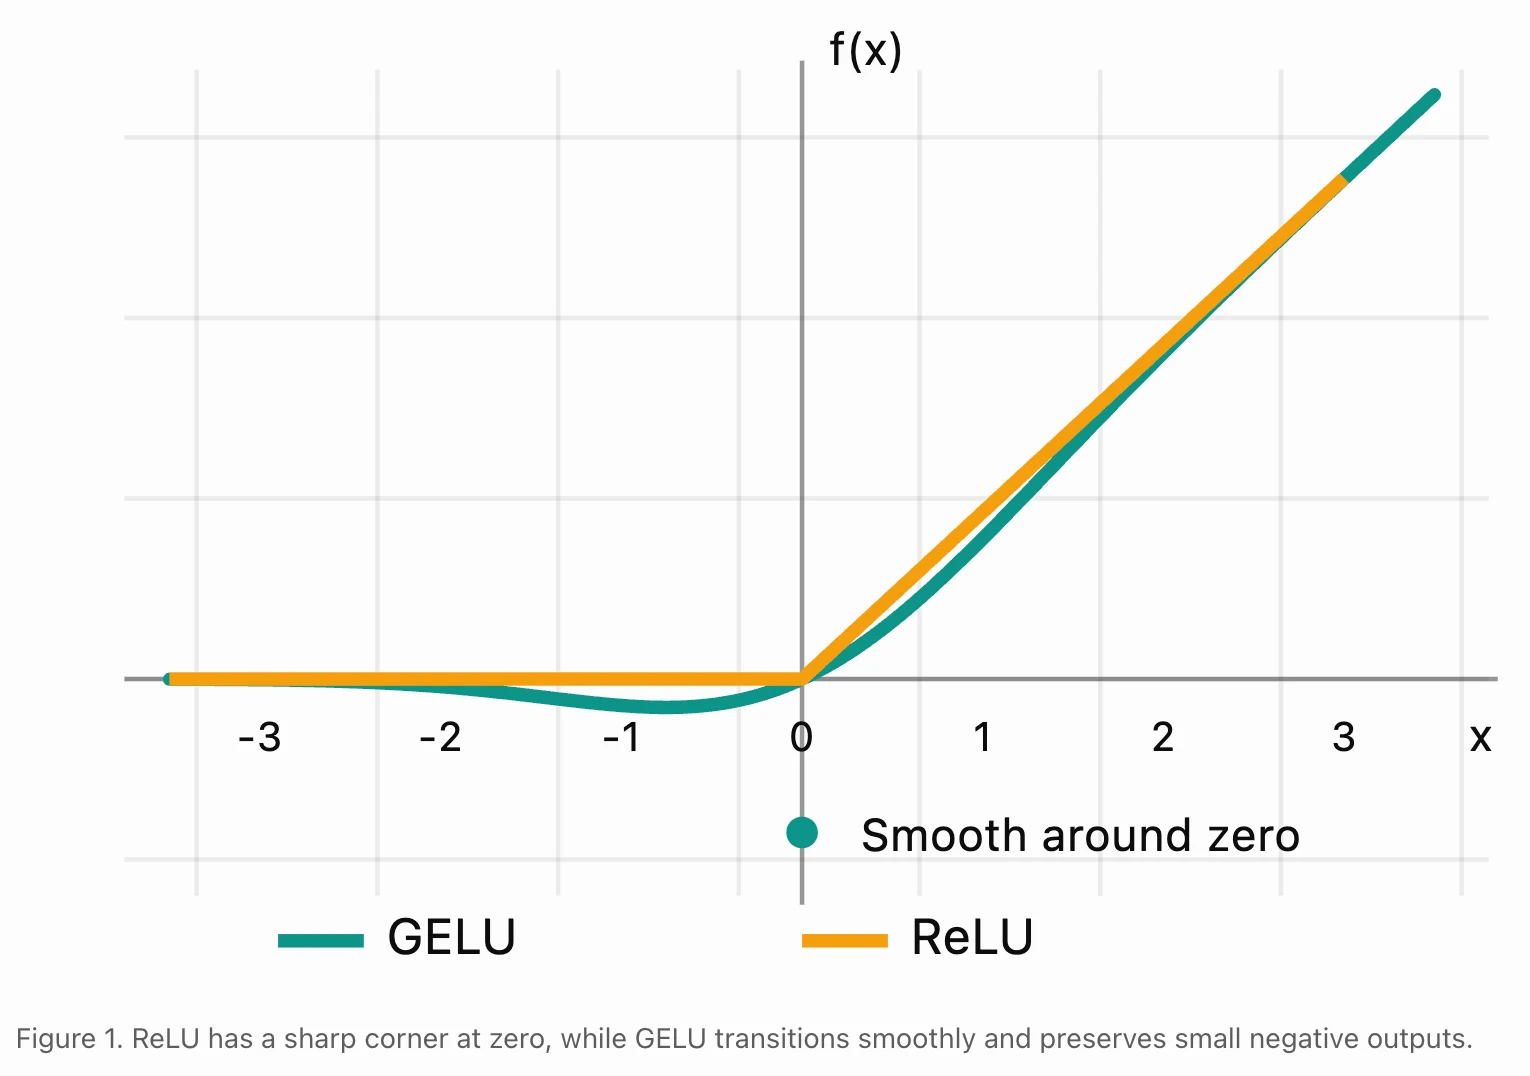
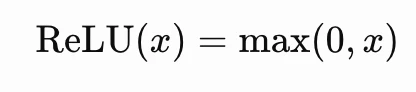
For an enter of -1, ReLU returns 0. For an enter of two, it returns 2.
GELU behaves in another way. An enter of -1 produces roughly -0.159, whereas an enter of two produces roughly 1.954.
This implies GELU doesn’t merely classify inputs as constructive or unfavourable. It applies a steady transformation that scales completely different values by completely different quantities.
Importantly, GELU shouldn’t be strictly rising over its complete area. Its unfavourable area has a shallow dip earlier than approaching zero for very unfavourable inputs.
The Arithmetic Behind GELU
The GELU activation operate is outlined as:
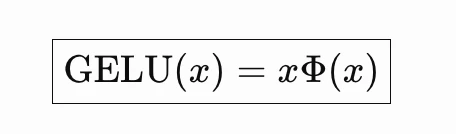
Right here, Φ(x) represents the cumulative distribution operate (CDF) of the usual regular distribution.
The usual regular distribution has a imply of zero and a regular deviation of 1.
We will write its CDF as:
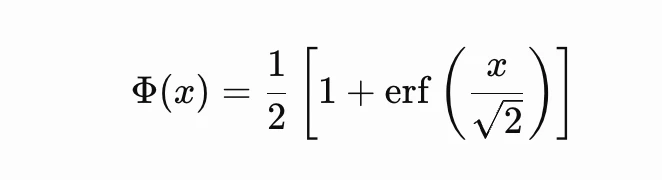
Due to this fact, GELU may also be expressed as:
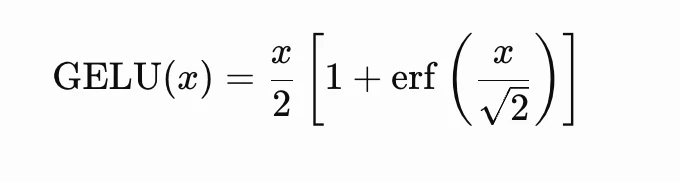
Right here, erf is the error operate, a mathematical operate carefully associated to the Gaussian distribution.
A easy numerical instance
Suppose a neuron receives an enter of 1.
The usual regular CDF at 1 is roughly 0.8413.
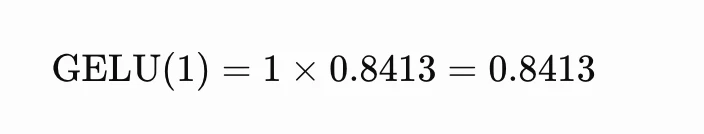
Now think about an enter of -1.
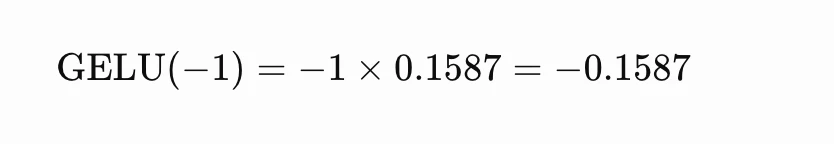
Discover that the constructive enter is usually preserved, whereas the unfavourable enter is considerably diminished.
This easy habits is the central concept behind GELU.
Why Does GELU Use a Gaussian Distribution?
The Gaussian distribution supplies a easy solution to assign weights to completely different enter values.
For giant unfavourable inputs, the CDF approaches zero. For giant constructive inputs, it approaches one. At zero, its worth is precisely 0.5.
Determine 2. The Gaussian CDF supplies a gradual weighting issue between 0 and 1.
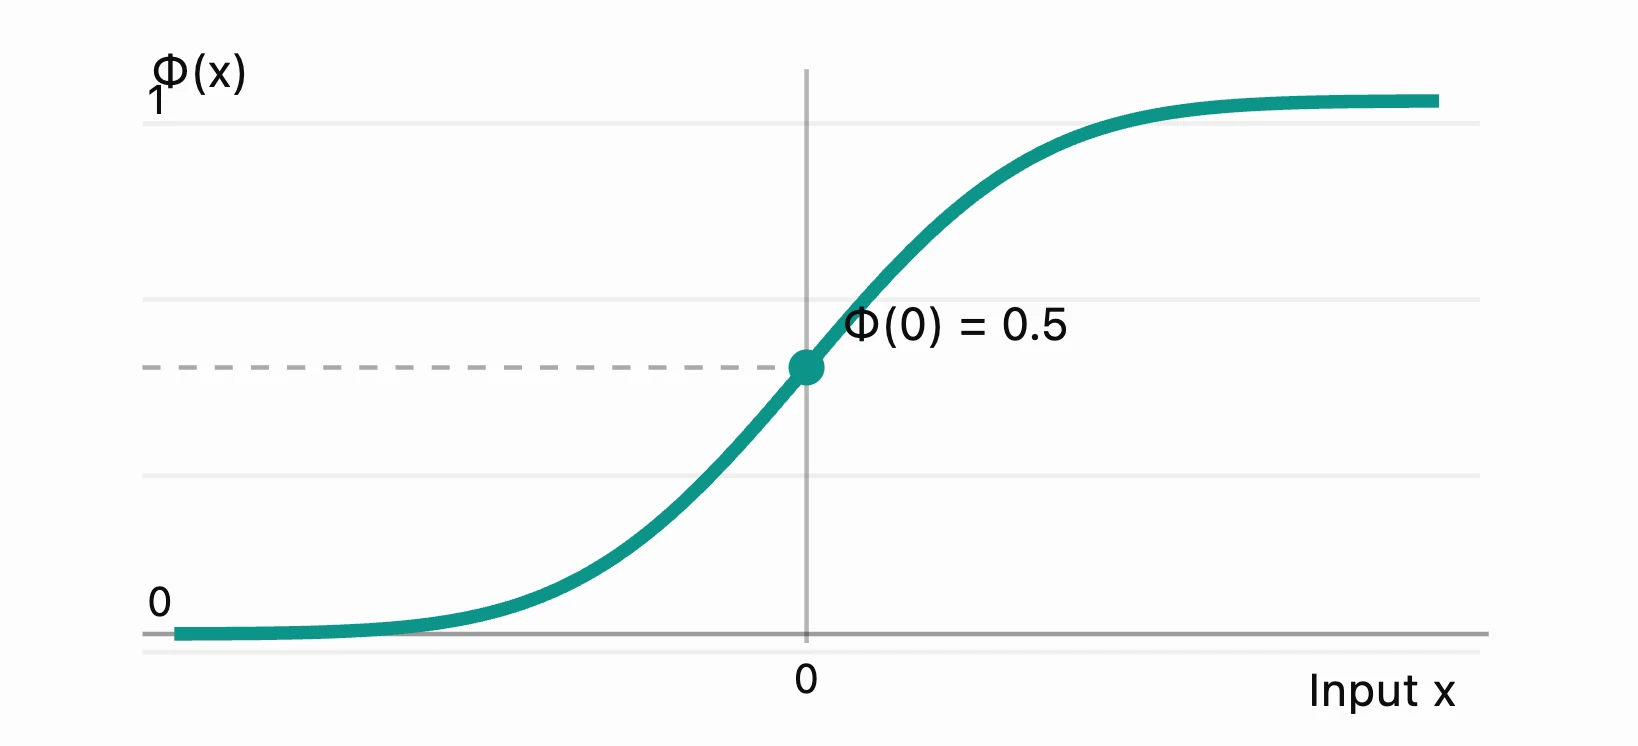
The important thing distinction is that the Gaussian CDF acts as a scaling issue moderately than a binary swap.
That is typically defined as a probabilistic gating mechanism. Nonetheless, customary GELU is deterministic. It doesn’t randomly take away neuron outputs throughout execution.
GELU vs ReLU: Key Variations
| Function | ReLU | GELU |
|---|---|---|
| Mathematical operation | max(0, x) | x × Φ(x) |
| Adverse inputs | Zeroed out | Easily suppressed |
| Smoothness | Not differentiable at zero | Clean and differentiable |
| Computation | Very cheap | Extra complicated |
| Output for x = 0 | 0 | 0 |
| Typical use | CNNs and light-weight MLPs | BERT-style Transformers and plenty of MLP blocks |
| Coaching efficiency | Sturdy baseline | Can outperform ReLU, relying on the duty |
ReLU stays standard as a result of it’s easy and computationally environment friendly. GELU supplies a smoother transformation however requires extra computation in its mathematical type.
GELU shouldn’t be routinely higher for each neural community. The mannequin structure, dataset, {hardware}, and implementation all have an effect on the ultimate consequence.
Why Is GELU Utilized in Transformers?
Transformers comprise a number of parts, together with consideration mechanisms, normalization layers, and feed-forward neural networks.
GELU is often used contained in the feed-forward community, or FFN, moderately than within the consideration likelihood calculation itself.
A simplified Transformer feed-forward operation appears like this:
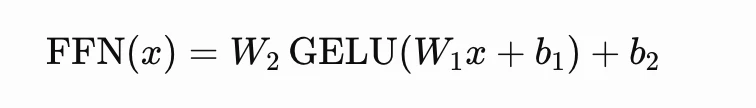
The primary linear layer tasks the hidden illustration into one other function area. GELU introduces nonlinearity, and the second linear layer tasks it again into the required hidden dimension.
Within the BERT structure, GELU is the default hidden activation, as mirrored in Hugging Face’s BERT configuration.
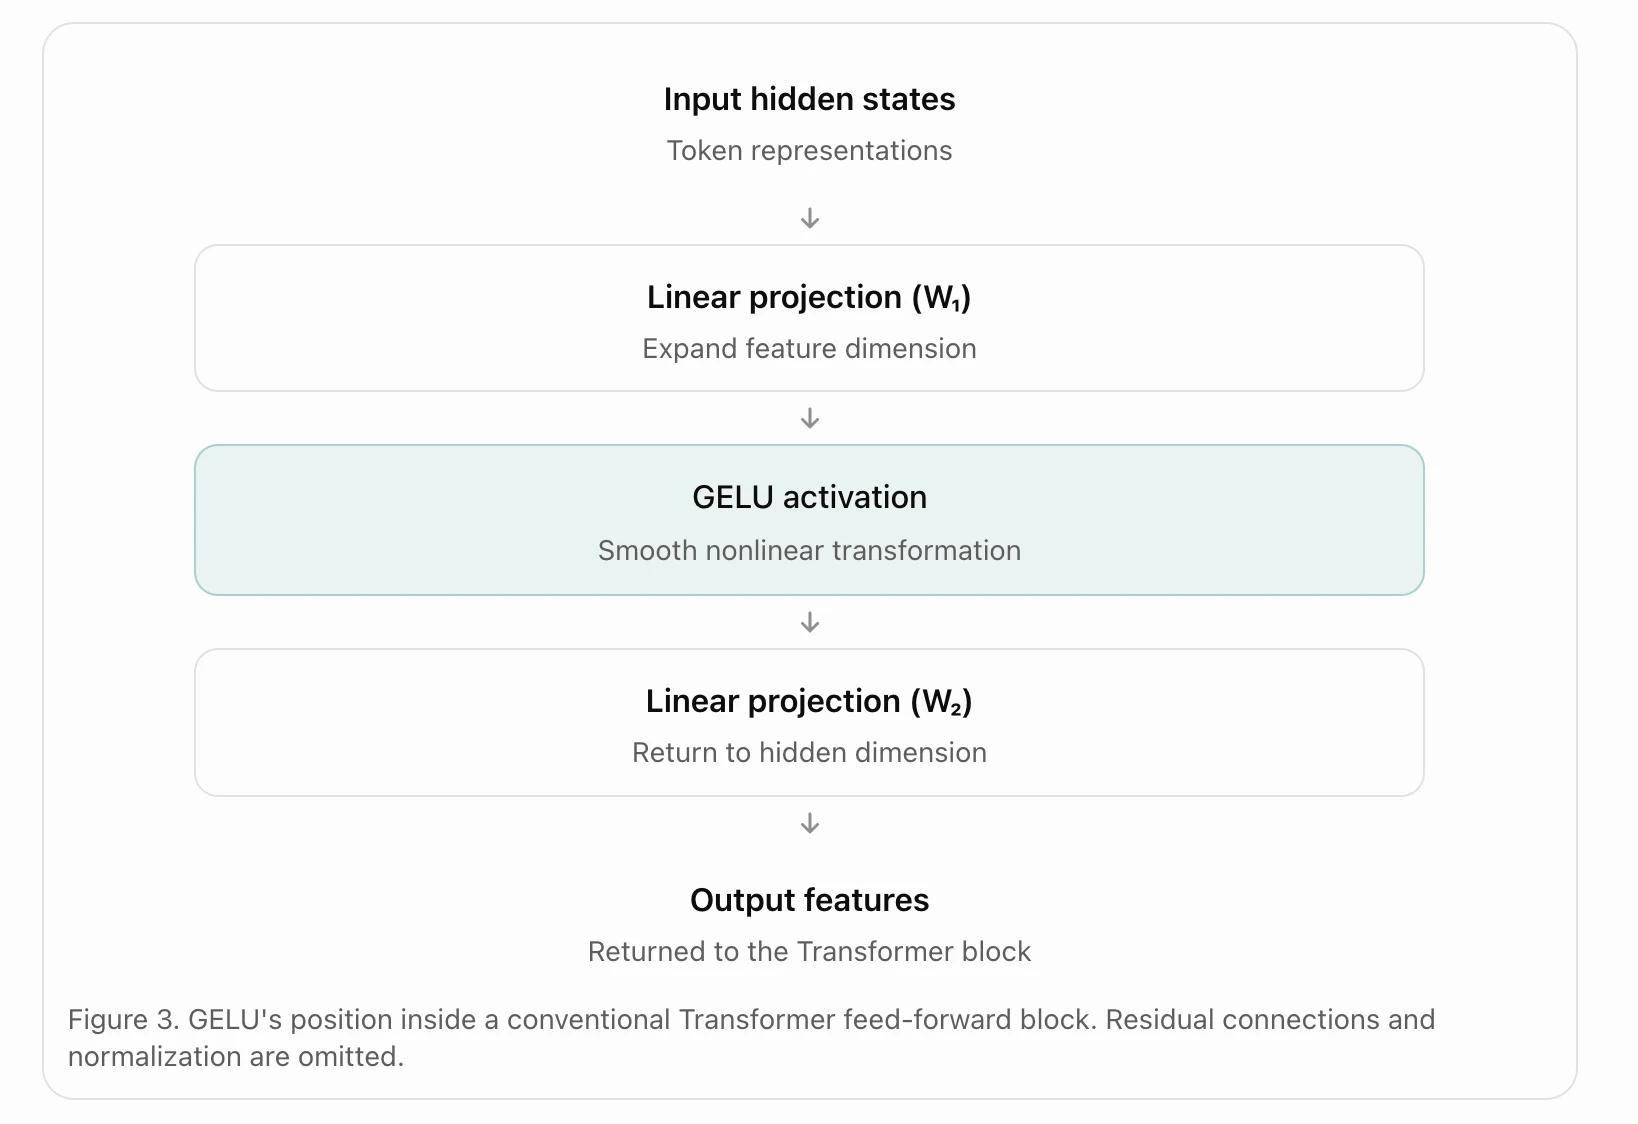
GELU additionally seems in imaginative and prescient Transformer architectures. Nonetheless, not all trendy language fashions use GELU. Some use SiLU-based gated feed-forward variants, similar to SwiGLU.
The selection depends upon the mannequin structure and its coaching targets.
Approximating GELU for Environment friendly Computation
The precise GELU method makes use of the Gaussian cumulative distribution operate, which will be extra computationally costly than easier activations.
A standard approximation makes use of the hyperbolic tangent operate:
This approximation produces values near actual GELU whereas offering another implementation which may be computationally environment friendly on sure {hardware}.
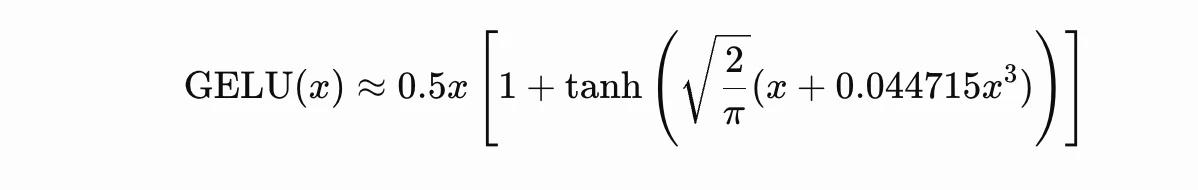
PyTorch helps each the precise formulation and the tanh approximation by way of the approximate parameter
Fingers-On: Evaluating GELU and ReLU Utilizing Python
Now that we perceive the idea, let’s discover how GELU behaves utilizing Python and PyTorch.
We’ll first visualize each activation capabilities after which examine their efficiency on a small classification downside.
Step 1: Set up the required libraries
pip set up torch numpy matplotlib scikit-learnStep 2: Visualize GELU and ReLU
import torch
import torch.nn.practical as F
import matplotlib.pyplot as plt

# Generate enter values
x = torch.linspace(-4, 4, 500)

# Apply activation capabilities
relu_output = F.relu(x)
gelu_output = F.gelu(x)

# Plot each capabilities
plt.determine(figsize=(9, 5))

plt.plot(x.numpy(), relu_output.numpy(),
         label="ReLU", linewidth=2)

plt.plot(x.numpy(), gelu_output.numpy(),
         label="GELU", linewidth=2)

plt.axhline(0, coloration="grey", linewidth=0.6)
plt.axvline(0, coloration="grey", linewidth=0.6)

plt.title("GELU vs ReLU Activation Capabilities")
plt.xlabel("Enter")
plt.ylabel("Output")
plt.legend()
plt.grid(alpha=0.3)
plt.present()
The graph reveals that ReLU fully removes unfavourable values, whereas GELU has a easy curve that retains some unfavourable outputs.
Step 3: Construct a easy neural community
Subsequent, we are going to practice two an identical neural networks. One will use ReLU, and the opposite will use GELU.
We’ll use the make_moons dataset as a result of its nonlinear choice boundary makes it helpful for testing neural networks.
import numpy as np
import torch
import torch.nn as nn

from sklearn.datasets import make_moons
from sklearn.model_selection import train_test_split
from sklearn.preprocessing import StandardScaler

# Set random seed
torch.manual_seed(42)

# Generate artificial classification knowledge
X, y = make_moons(
    n_samples=2000,
    noise=0.25,
    random_state=42
)

# Cut up knowledge into coaching and testing units
X_train, X_test, y_train, y_test = train_test_split(
    X,
    y,
    test_size=0.2,
    random_state=42,
    stratify=y
)

# Normalize utilizing coaching knowledge solely
scaler = StandardScaler()

X_train = scaler.fit_transform(X_train)
X_test = scaler.rework(X_test)

# Convert knowledge into PyTorch tensors
X_train = torch.tensor(X_train, dtype=torch.float32)
X_test = torch.tensor(X_test, dtype=torch.float32)

y_train = torch.tensor(y_train, dtype=torch.lengthy)
y_test = torch.tensor(y_test, dtype=torch.lengthy)


# Outline Neural Community
class NeuralNetwork(nn.Module):

    def __init__(self, activation):

        tremendous().__init__()

        self.community = nn.Sequential(

            nn.Linear(2, 64),

            activation(),

            nn.Linear(64, 64),

            activation(),

            nn.Linear(64, 2)

        )

    def ahead(self, x):

        return self.community(x)
Step 4: Prepare and examine the fashions
import torch
import torch.nn as nn
import torch.optim as optim
import matplotlib.pyplot as plt

def train_model(activation, epochs=100):

    torch.manual_seed(42)

    mannequin = NeuralNetwork(activation)

    optimizer = optim.Adam(
        mannequin.parameters(),
        lr=0.001
    )

    criterion = nn.CrossEntropyLoss()

    historical past = []

    for epoch in vary(epochs):

        # Coaching section
        mannequin.practice()

        optimizer.zero_grad()

        outputs = mannequin(X_train)

        loss = criterion(outputs, y_train)

        loss.backward()

        optimizer.step()

        # Analysis section
        mannequin.eval()

        with torch.no_grad():

            predictions = mannequin(X_test).argmax(dim=1)

            accuracy = (
                predictions == y_test
            ).float().imply().merchandise()

        # Retailer accuracy after each epoch
        historical past.append(accuracy)

    return mannequin, historical past


# Prepare utilizing ReLU activation
relu_model, relu_history = train_model(nn.ReLU)

# Prepare utilizing GELU activation
gelu_model, gelu_history = train_model(nn.GELU)


# Print ultimate accuracies
print(f"ReLU Accuracy: {relu_history[-1]:.4f}")
print(f"GELU Accuracy: {gelu_history[-1]:.4f}")


# Plot studying curves
plt.determine(figsize=(9, 5))

plt.plot(relu_history, label="ReLU")
plt.plot(gelu_history, label="GELU")

plt.xlabel("Epoch")
plt.ylabel("Check Accuracy")
plt.title("ReLU vs GELU: Studying Comparability")

plt.legend()
plt.grid(alpha=0.3)

plt.present()
Step 5: Interpret the outcomes
After working the experiment, examine the ultimate take a look at accuracy and studying curves.
You would possibly observe that GELU achieves barely increased accuracy, converges in another way, or performs equally to ReLU. There isn’t any assured winner.
Each fashions have the identical community structure, optimizer, studying fee, and initialization seed. The activation operate is the first distinction.
Nonetheless, a single coaching run shouldn’t be sufficient to ascertain which activation is best. For a extra dependable comparability, repeat the experiment with a number of random seeds and examine the common accuracy and customary deviation. Throughout experimentation, a validation set ought to be used for mannequin choice, with the take a look at set reserved for ultimate analysis.
The objective of this experiment is to know how altering an activation operate can affect mannequin habits, to not show that GELU is universally superior.
Benefits and Limitations of GELU
GELU supplies a number of helpful properties, however it additionally introduces trade-offs.
Benefits
- Clean activation habits, together with round zero.
- Preserves some info from reasonably unfavourable inputs.
- Absolutely differentiable, making gradient-based optimization simple.
- Efficiently utilized in established Transformer architectures.
- Supported by main deep studying frameworks.
Limitations
- Extra mathematically complicated than ReLU.
- Could require further computation, relying on implementation and {hardware}.
- Doesn’t assure higher accuracy or sooner convergence.
- Clean gradients don’t remove all vanishing-gradient issues.
- Is probably not mandatory for small or latency-sensitive fashions.
One essential mathematical property is GELU’s by-product:
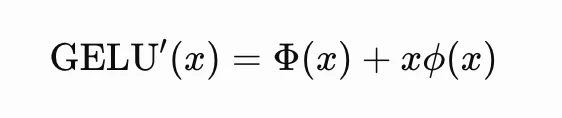
Right here, Phi(x) is the usual regular likelihood density operate.
In contrast to ReLU, GELU has a by-product at zero. Nonetheless, this doesn’t imply its by-product is all the time constructive or that gradients all the time stay massive.
When Ought to You Use GELU?
GELU is an efficient place to begin when constructing Transformer-style fashions, notably when following an structure that already makes use of it.
ReLU continues to be a superb default for a lot of typical feed-forward networks, convolutional networks, and functions the place computation price issues.
For a pretrained mannequin, protecting its unique activation operate is mostly the most secure selection. Changing GELU with ReLU in a pretrained Transformer modifications the mannequin’s computations and will scale back its efficiency except the modified mannequin is appropriately retrained or fine-tuned.
In new architectures, deal with the activation operate as a design selection that ought to be evaluated experimentally.
Conclusion
GELU improves on the straightforward thresholding strategy of ReLU by introducing easy, input-dependent scaling. Its use of the Gaussian cumulative distribution operate makes it attainable to protect small unfavourable indicators whereas regularly suppressing strongly unfavourable inputs.
This habits has made GELU an essential part of a number of influential Transformer architectures.
Nonetheless, its worth shouldn’t be merely that it’s smoother or extra mathematically subtle. Its sensible effectiveness depends upon the whole neural community, the coaching setup, and the {hardware}.
Understanding GELU supplies a helpful basis for learning trendy neural networks and the design selections behind Transformer feed-forward layers.
Learn extra: Mamba4 Defined: A Sooner Different to Transformers for Sequential Modeling
Ceaselessly Requested Questions
A. ReLU acts as a tough threshold by zeroing out unfavourable values, whereas GELU applies a easy, steady scaling primarily based on the enter’s worth utilizing a Gaussian distribution.
A. GELU supplies a smoother, differentiable transformation that helps neural networks be taught complicated patterns extra successfully, which is why it’s the default in architectures like BERT.
A. The precise method is extra complicated than ReLU, however builders typically use a hyperbolic tangent approximation to attain comparable outcomes with higher computational effectivity on particular {hardware}.

Hello, I’m Janvi, a passionate knowledge science fanatic at present working at Analytics Vidhya. My journey into the world of information started with a deep curiosity about how we will extract significant insights from complicated datasets.
Login to proceed studying and luxuriate in expert-curated content material.